The fastest way to extract data from emails is an automated parser that combines rule-based rules for stable templates with AI or OCR fallback for anything variable. Route output straight to a spreadsheet, CRM, or accounting system. Rule-based parsing wins on cost and speed when your senders never change format; AI-based extraction wins when formats vary, but it costs more per document and needs occasional human review.
TL;DR:
- Rule-based parsing is ideal when email templates rarely change, offering a low-cost, fast solution but requiring manual updates after any format change.
- AI or OCR-based extraction suits high-variability formats and attachments, but it incurs higher costs and needs human review for accuracy.
- Building an effective workflow involves selecting a trigger, mapping fields before setup, testing thoroughly, and implementing confidence thresholds for ongoing accuracy.
- Extracted data should be directed to systems like CRMs, spreadsheets, or accounting platforms with careful handling of missing fields, duplicates, and access controls.
- Scaling costs include per-document AI or OCR fees, engineering maintenance, and human review, with hybrid approaches often balancing expenses and coverage for solo professionals.
Table of Contents
- What Is Email Data Extraction and Why It Matters
- Rule-Based Parsing vs. Scripts vs. AI: Which One Fits?
- How Do You Set Up an Email Extraction Workflow?
- How Do You Extract Data From PDFs and Scanned Attachments?
- Where Should Extracted Data Go?
- How Do You Keep Extraction Accurate Over Time?
- What Does Email Extraction Cost as You Scale?
- How Rooted Up Approaches Email Extraction for Solo Professionals
- Should You Build This Yourself or Hire It Out?
- Get an Email Extraction Pilot Without the Engineering Overhead
- Sources
- FAQ
What Is Email Data Extraction and Why It Matters
Email data extraction turns unstructured content sitting in a message body, an attachment, or the message headers into structured rows and columns you can actually use. That means pulling an invoice number out of a PDF, a shipping address out of an order confirmation, or a phone number out of a lead inquiry, and dropping each into its own field rather than leaving it buried in prose. Lido's breakdown of the process frames this as the core function: convert body text, attachments, and metadata into structured output that flows into spreadsheets, CRMs, or accounting platforms.
For a solo professional or a small operations team, this matters because email is still where most business actually happens. Leads arrive as inquiry forms forwarded to a shared inbox. Vendors send invoices as PDF attachments. Booking confirmations, support tickets, and payment notifications all land in the same place, and somebody has to retype that information into a system of record. Automated extraction removes that retyping step, and it does it whether the data lives in the email body or in a scanned attachment.
Rule-Based Parsing vs. Scripts vs. AI: Which One Fits?
Three technical approaches dominate this space, and each one fits a different mix of volume, format variability, and budget.
Rule-based parsing relies on templates and regular expressions to locate fields at consistent positions. If your supplier always sends the same invoice layout with the total in the same spot, a rule-based parser reads it reliably and cheaply. The catch: any layout change breaks the rule, and you're back in the editor rebuilding it.
Custom scripts give you full control. A Python script using a mailbox library can log into an inbox, pull messages by criteria, and apply whatever logic you want. This suits teams with in-house engineering time and unusual requirements a commercial tool won't cover, but scripts need ongoing maintenance every time a sender tweaks their template or an API changes.
AI and intelligent document processing (IDP) combine optical character recognition, natural language processing, and increasingly large language models to read documents the way a person would rather than by fixed position. Generative AI can extract tabular data from emails and attachments without a template at all, which matters when you receive invoices from fifty different vendors in fifty different formats. Microsoft's Azure AI Foundry team documents this pattern as a way to skip custom parsing work entirely for variable formats.
A simple way to pick:
- Low volume, one template, no compliance pressure → rule-based parsing.
- Custom logic, engineering staff on hand, unusual data sources → custom scripts.
- High format variability, attachments in mixed formats, or regulated data → AI/IDP with human review built in.
Pro Tip: Don't pick one approach and lock in. That hybrid keeps your per-document cost low without sacrificing coverage.
How Do You Set Up an Email Extraction Workflow?
Building a working extraction pipeline is mostly a sequencing problem. Get the order right and each step sets up the next one cleanly.
- Pick your trigger. Three common patterns work: a dedicated mailbox that only receives the emails you want parsed, a forwarding rule that routes matching messages from an existing inbox, or a label/filter watcher inside Gmail or Outlook that flags messages for processing without moving them. A dedicated parser inbox is usually the cleanest starting point because it keeps parsing logic separate from your regular correspondence.
- Document the fields you need. Build a mapping table before you touch any tool. List every field (invoice number, vendor name, line items, due date), its source (body or attachment), and its destination column.
- Choose your parsing approach and build it out. For rule-based tools, write the extraction rules against real sample emails. For AI-based tools, collect a training set of 15 to 20 representative messages covering your format variety.
- Connect the destination. Map each extracted field to its column in Google Sheets, its record in a CRM, or its line item in an accounting platform.
- Test before you trust it. Send sample emails through the full pipeline, including edge cases: missing fields, unusual formatting, attachments with poor scan quality.
Fields worth mapping in almost every setup:
- Sender email and name
- Subject line and received timestamp
- Core transactional fields (amount, date, ID number)
- Attachment presence and file type
- A confidence or status flag for downstream review
Configure an error-handling path before you go live, not after. Anything below your confidence threshold should land in a review queue instead of flowing straight into your CRM.
How Do You Extract Data From PDFs and Scanned Attachments?
Attachments are where most of the real business data actually lives, and they demand more work than parsing plain text. Invoices, receipts, and scanned intake forms usually arrive as PDFs or images, which means OCR has to convert pixels into readable text before any field extraction can happen. Industry guidance on automated email data extraction points out that OCR combined with NLP is core to reliably pulling structured fields out of these documents, since the important numbers rarely sit in the email body itself.
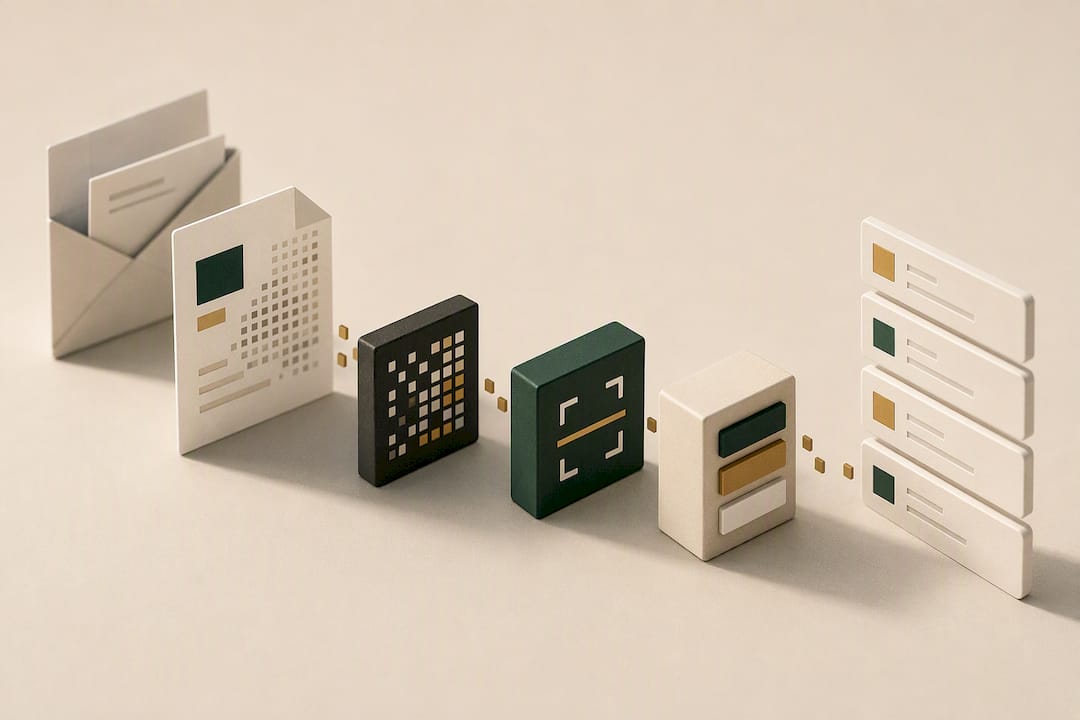
Single-field extraction (pulling one invoice total) is straightforward compared to table or line-item extraction, where a parser has to recognize row and column structure across multiple items, quantities, and prices that may span several pages. That's a materially harder problem, and it's where AI-based table extraction tends to outperform rigid rule-based templates.
Watch for these quality issues:
- Low scan resolution garbles character recognition, especially on small print like tax IDs.
- Rotated or skewed pages confuse OCR engines that expect upright text.
- Non-standard fonts or handwriting on intake forms drop accuracy sharply.
- Multi-page tables that split a single line item across two scanned pages.
Statistic Callout: Generative AI and IDP pipelines can read both email bodies and attachments in a single pass, extracting fields, summarizing content, and classifying documents automatically, according to AWS's overview of generative AI for email automation. That single-pass capability is what makes OCR plus AI worth the added cost for attachment-heavy workflows.
Cross-check line-item totals against the invoice grand total as a built-in validation step. If they don't match, flag the document for review before it ever reaches your accounting system.
Where Should Extracted Data Go?
The destination matters as much as the extraction method. Send data somewhere it can't be used, and the whole pipeline was wasted effort.
Common export targets include Google Sheets and Excel or CSV for lightweight tracking, CRMs for lead and customer data, accounting platforms for invoices and payments, relational databases for larger operations, and webhooks or APIs when you need to trigger a downstream action rather than just store a value.
Good mapping practice means deciding in advance what happens when a field is missing. Does the record still get created with a blank, or does it route to a review queue? Guessing at runtime creates inconsistent data.
- Build idempotency checks so a re-sent email doesn't create a duplicate record.
- Handle email threads carefully. A reply chain with five messages should usually update one record, not create five.
- Restrict access to sensitive fields (bank details, medical information) using minimal-permission integrations rather than blanket inbox access.
- Log every write so you can trace a bad record back to its source email.
Getting duplicate and thread handling wrong is the most common reason a technically accurate parser still produces a messy destination system.
How Do You Keep Extraction Accurate Over Time?
Accuracy isn't a one-time setup task. It's an ongoing measurement problem, and the tools that treat it that way stay reliable longer.
- Set a confidence threshold. Every extracted field should carry a confidence score. Anything below your threshold routes to a human reviewer instead of flowing straight to the destination system.
- Build automated validation rules. Cross-check totals, verify date formats, confirm required fields are populated before a record is considered complete.
- Sample your output regularly. Pull a random 5% of processed emails each week and manually verify them against the source.
- Track your error rate against an SLA target. Decide what error rate is acceptable for your use case, then monitor against it.
- Log corrections. When a human reviewer fixes a bad extraction, log the correction. That log becomes your audit trail and your training data for improving the parser.
Human-in-the-loop review is standard practice for regulated industries or any low-confidence extraction, and AWS's guidance on financial workflow automation treats it as a required stage rather than an optional safety net.
Pro Tip: Review your correction log monthly, not just when something breaks. A pattern of the same field failing repeatedly usually means a template changed upstream, and catching that early saves weeks of quietly bad data.
What Does Email Extraction Cost as You Scale?
Cost breaks into four buckets: per-parse fees for AI-based extraction, OCR processing costs for attachments, the engineering time to build and maintain integrations, and the ongoing labor of human review for flagged items. Rule-based parsing carries almost no per-document cost once built, but every template change means manual rework. AI-based parsing costs more per document, yet it absorbs format changes without a rebuild, which often makes it cheaper over a year even at a higher unit price.
Cost drivers worth budgeting for:
- Per-parse AI or IDP fees, typically billed per document or per page.
- OCR processing for scanned attachments, which usually adds a small per-page cost.
- Integration engineering time, front-loaded but recurring when destination systems change.
- Human review labor for exceptions and low-confidence items.
The scaling path that works for most teams: pilot with a small volume on one or two senders, run a hybrid model once you've confirmed accuracy, then expand to full automation once your error rate holds steady for a few weeks.
How Rooted Up Approaches Email Extraction for Solo Professionals
Email extraction engagements typically run in three phases. First, an inbox audit maps what actually arrives, which senders matter, and which fields are worth extracting. Second, a mapping specification documents every field and its destination, followed by a pilot combining rule-based parsing with AI fallback for anything variable. Third, a QA and handoff phase confirms accuracy before the workflow runs unattended.
During a pilot, the metrics worth watching are time saved per week, the error rate on extracted fields, and lead capture rate for inquiry-driven inboxes. Solo professionals juggling client work and administrative overhead rarely have the bandwidth to build and babysit this themselves, which is exactly the gap a managed AI workflow closes.
— Jason
Should You Build This Yourself or Hire It Out?
Building this in-house makes sense when your monthly volume is low, your senders use stable templates, and you have someone with real engineering bandwidth to maintain rules as formats shift. If any one of those isn't true, especially format variability or compliance pressure on sensitive fields, a managed provider usually pays for itself faster than a DIY build.
Signs you should hire it out: your inbox volume keeps growing, nobody on staff wants to own the parser, or you've already had a bad month from a broken extraction rule nobody caught. When evaluating a provider's pilot proposal, check for three things: a clear mapping specification before any coding starts, a defined error rate target, and a review process for low-confidence extractions. A proposal missing any of those three is missing the part that actually keeps the system accurate.
Get an Email Extraction Pilot Without the Engineering Overhead
A managed service handles this the way solo professionals actually need it handled: audit your inbox, document the mapping spec, run a pilot combining rule-based parsing with AI fallback, then hold a regular QA cadence so accuracy doesn't quietly slip over time.
If you've read this far, you already know the DIY path works, but it takes engineering time most solo practices don't have lying around. This can be integrated into a monthly plan that also handles Google Business Profile, review automation, and administrative AI workflows, so your inbox data extraction gets ongoing attention alongside other services. Rather than choosing between a custom script nobody maintains and an expensive per-seat enterprise IDP tool, you get a pilot sized for a solo practice, with a human checking the output. If your team also sends outbound campaigns, AI email drafting fits the same workflow in reverse. Check current service packages to see what a pilot engagement would cover for your inbox.
Sources
For readers who want the underlying documentation rather than a summary, a few primary sources cover the technical detail this guide compresses. AWS's walkthrough of generative AI for email automation explains IDP pipelines and human review in more depth. Microsoft's Azure AI Foundry post shows working patterns for structured extraction without templates. Mailparser's setup guide walks through the mechanics of building a parser inbox from scratch. For readers building broader marketing automation around extracted lead data, AmmarAI's guide to practical AI use in marketing is worth a look.
- Streamline financial workflows with generative AI for email automation | Artificial Intelligence
- Use generative AI to extract structured data out of emails
- Your 101 Guide to Email Data Extraction (And How to Begin)
FAQ
Can I download my entire email history?
Most email providers let you export your full mailbox as an archive file (Gmail's Takeout tool and Outlook's export function both support this), but that gives you raw messages, not structured data. You still need a parsing step to turn that archive into usable fields.
How can I extract data from emails and export it to Excel?
Set up a parser, whether rule-based or AI-based, to pull the fields you need, then map the output directly to a CSV or Excel destination. Most parsing tools support a direct spreadsheet connection so no manual export step is needed.
Is there a free email extractor available?
Free tiers exist for basic rule-based parsing on low volumes, and Gmail's own filters and scripts (via Google Apps Script) can handle simple extraction for free with some setup work. Free options tend to break down once formats vary or volume grows past a few hundred emails a month.
Can you export a list of emails to Excel?
Yes. A parser can pull sender, subject, date, and any extracted fields into a spreadsheet row per email, which works well for tracking inquiries, orders, or support tickets in one place without manual copying.